Overview
Flows are visual data pipelines that transform, clean, and analyze your data without writing code. You add nodes to a canvas and connect them to build reusable transformations, from a simple filter to a multi-source analysis. Think of a Flow as:- A visual query builder that does not require SQL knowledge
- A reusable data transformation recipe
- Automated data preparation for your dashboards and reports
How Flows Work
A Flow is a chain of nodes laid out top to bottom. Data enters from an input node, passes through processing nodes, and lands in an output node.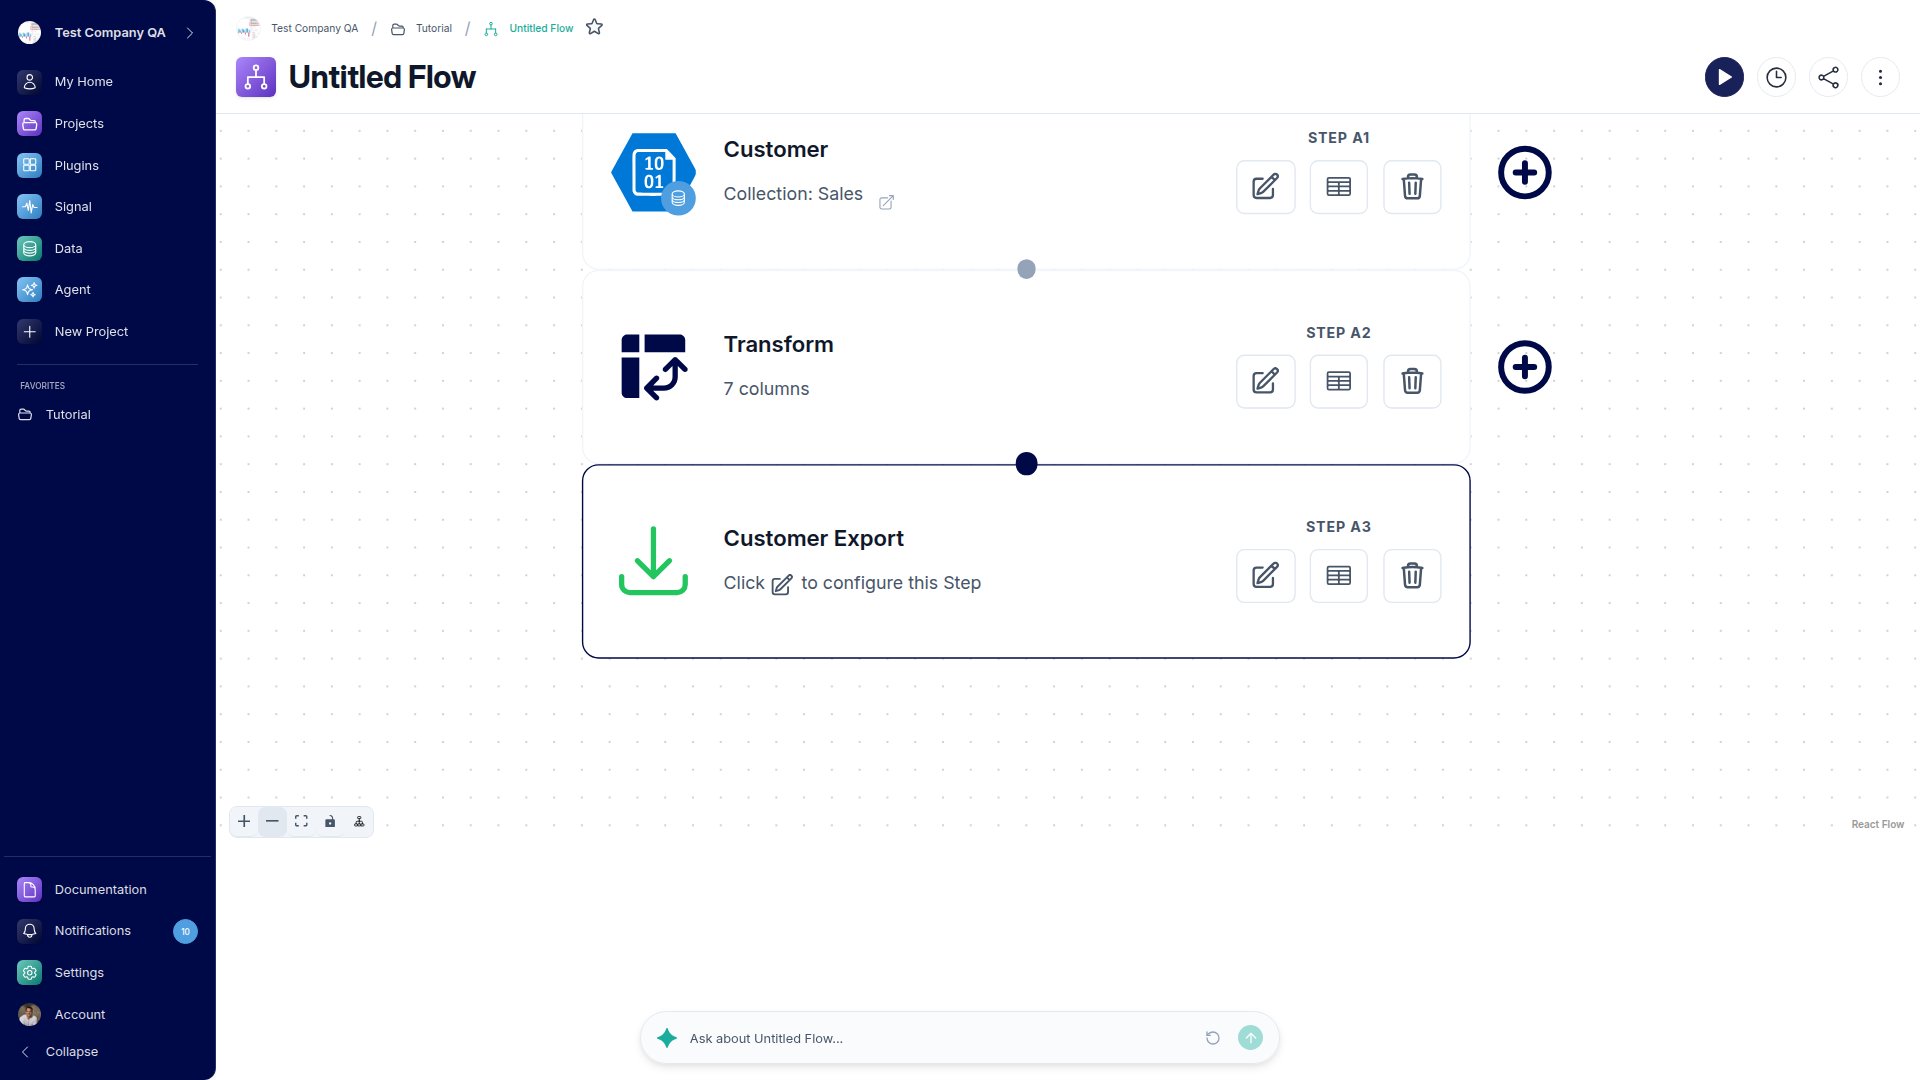
Creating a New Flow
1
Open your project
From the left sidebar, click Projects and select the project where you want the Flow.
2
Create the Flow
Click + Add Flow. The Flow opens on the canvas named “Untitled Flow”. Rename it from the top bar.
3
Add your first node
Click + Add node, then choose Get Data to pull in a table to start from.
The Node Palette
Click + Add node to open the palette. It is a searchable popover, so you can type a name or what you want to do (try “join” or “pivot”) to find the right node. Nodes are grouped into five sections: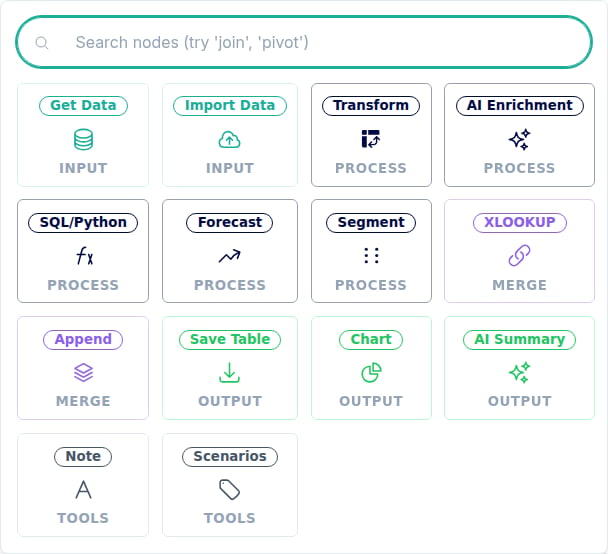
- Get Data - pull rows from a connected table or Virtual Table
- Import Data - upload a CSV or spreadsheet straight into the Flow
- Transform - filter, sort, group, aggregate, pivot, and add fields
- AI Enrichment - use AI to add, classify, or extract fields
- SQL/Python - run a custom SQL query or Python script
- Forecast - project future values from a time series
- Segment - group rows into clusters by similarity
- Save Table - persist the result as a Virtual Table
- Chart - render a chart from the data
- AI Summary - narrate the data with an AI summary
Most data shaping happens in the Transform node. It combines what used to be separate filter, sort, group, pivot, and formula nodes into one place.
Connecting and Configuring Nodes
To connect two nodes, drag from the handle at the bottom of one node to the top of the next. To configure a node, click the pencil icon to open its modal, set it up, and save. To remove a connection, click the line and press Delete.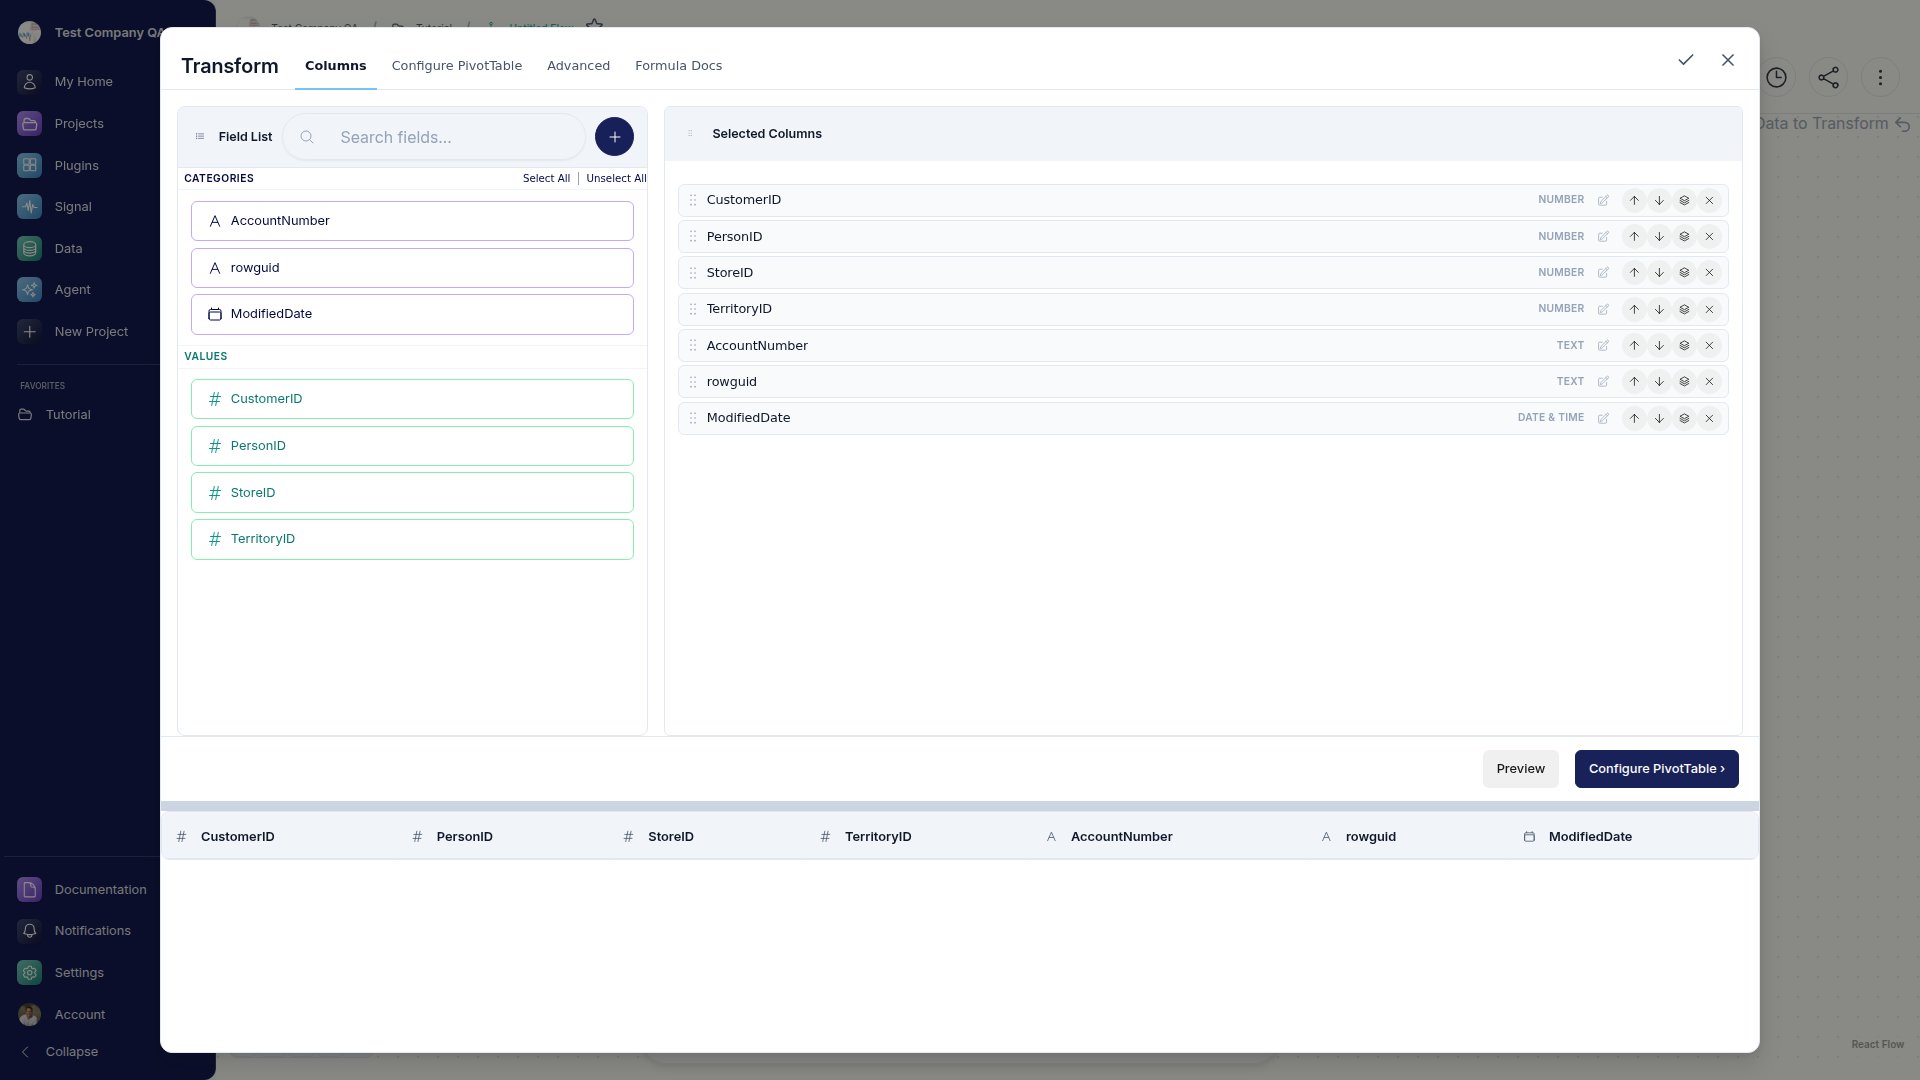
Previewing Data
Click the preview icon on any configured node to see its output up to that point.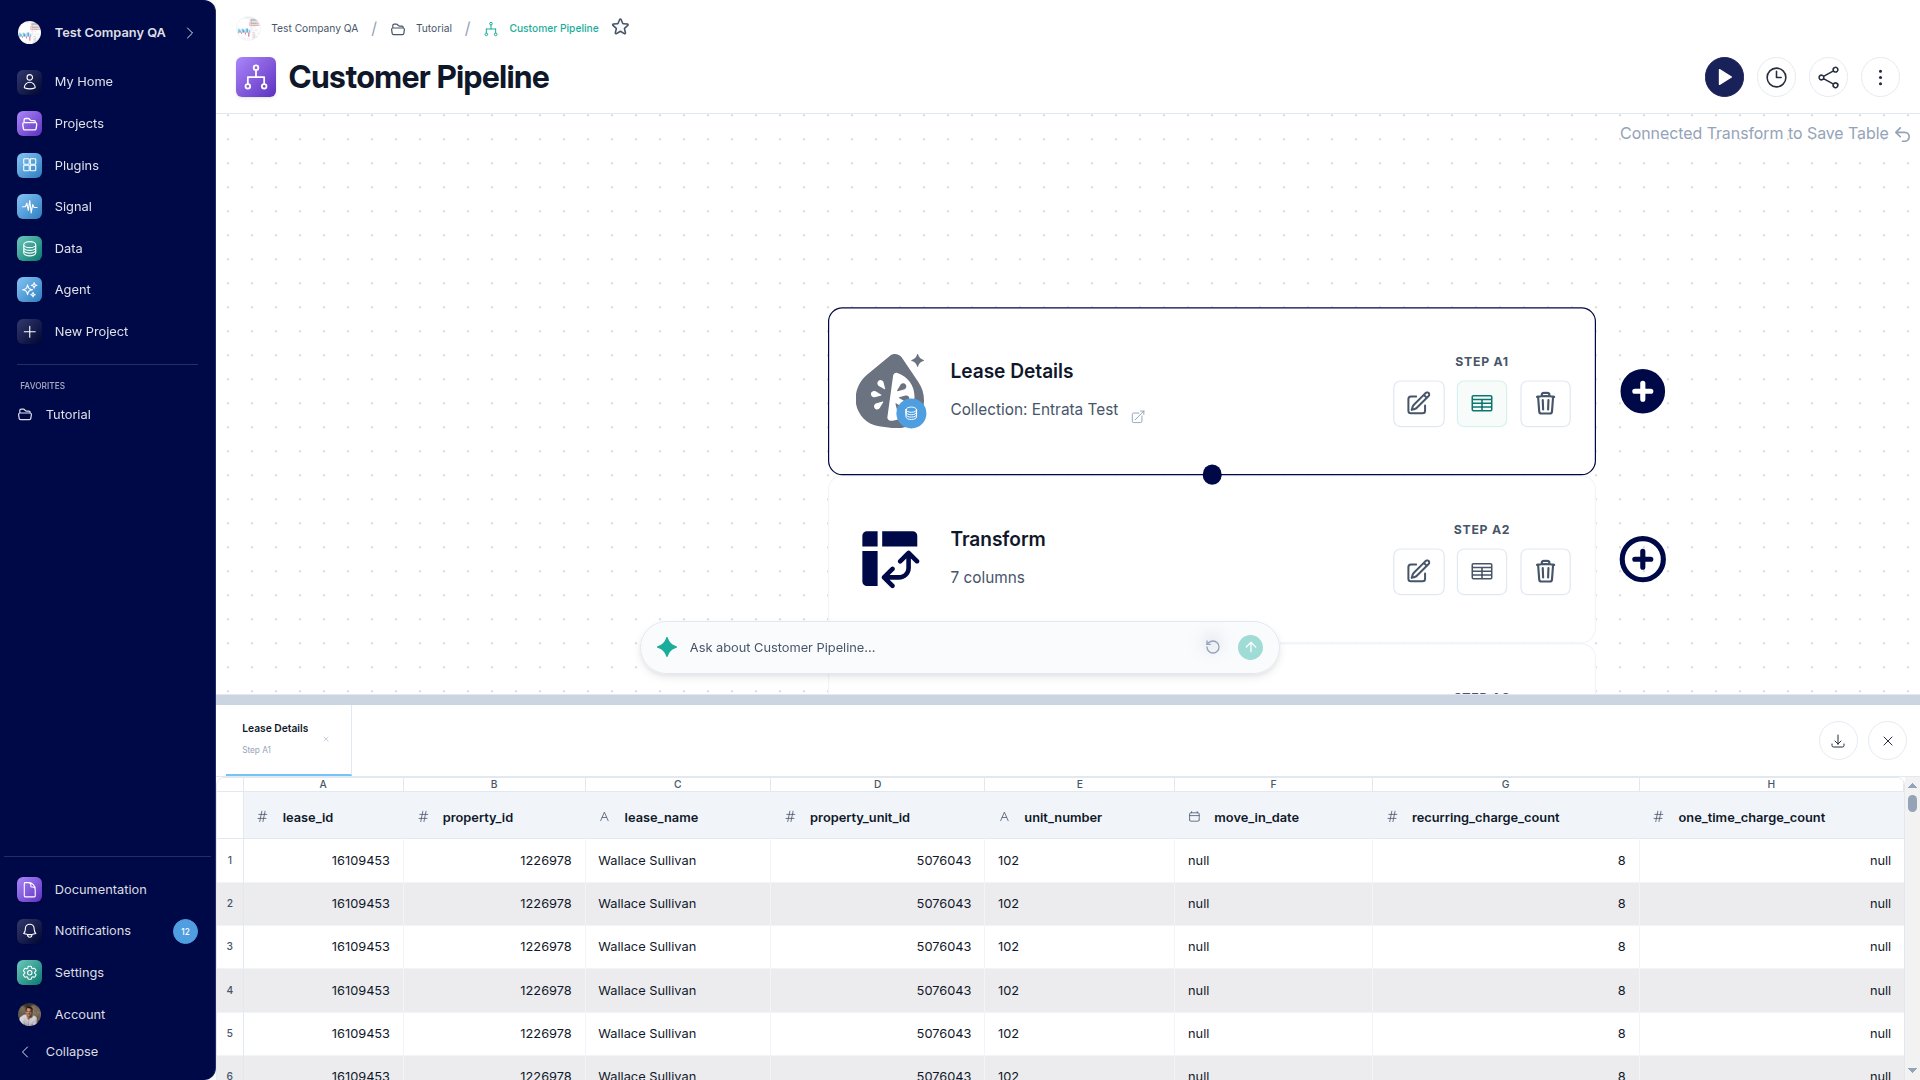
Previews run on a sample of your source data to keep things fast. If a node returns 0 rows in the preview, a banner notes the preview used a limited sample and the full dataset may still match. Run the Flow to see results across all your data.